In this article
The short answer: prompt-prefix caching is worth deploying when a long, stable context is reused at meaningful volume—but cache-hit rate is not the business outcome. Compare realized input cost, latency, accepted-output quality and the risk of reusing stale context. Put stable instructions and examples first, changing business data last, and measure cost per accepted outcome.
OpenAI’s official prompt-caching documentation states that GPT-5.6 and later require at least 1,024 visible input tokens to cache a prefix. As of 27 September 2026, a cache write is charged at 1.25 times ordinary input and a cache read at 0.1 times that rate. These are provider- and model-specific terms that can change; they should not be assumed for another platform.
Distinguish two types of cache
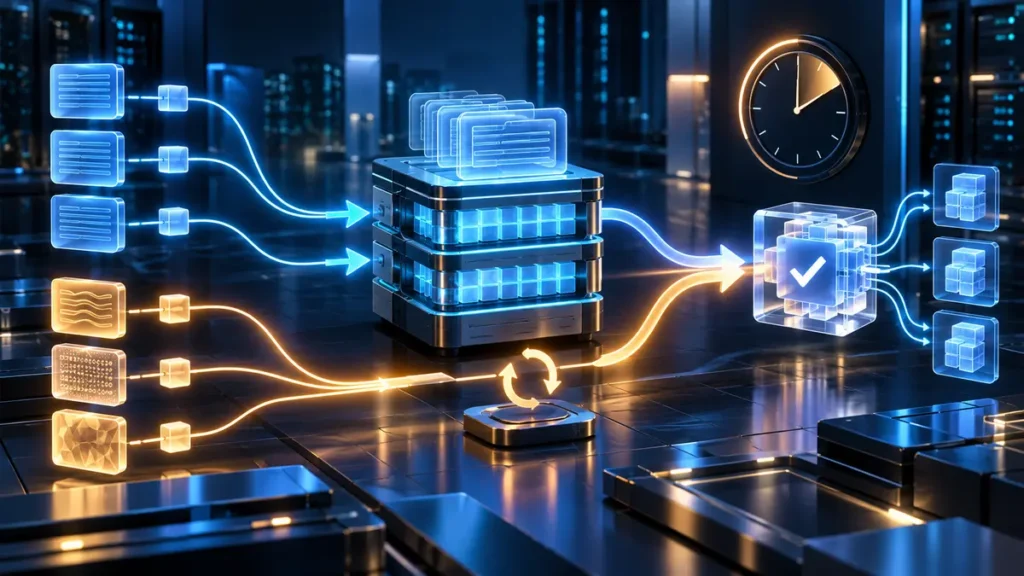
Provider-side prefix caching reuses computation for identical instructions, schemas or documents at the start of a request while the model still generates a fresh response. Application response caching returns a previous answer for an exact or similar question. The second can save more, but it also creates greater staleness and context risk.
Start with prefix caching when answers must be current or auditable. Cache complete answers only when the business can define an expiry window, tenant separation and invalidation rules for changes in price, stock, policy or customer data.
Hypothetical example: 10,000 requests per month
Assumptions: each request contains a 1,200-token stable prefix and 800 variable tokens. The prefix cache is hit on 70% of requests and rewritten 30 times in the month. The example uses the published GPT-5.6 multipliers and excludes output tokens because they are unchanged by the comparison.
- Without caching: 10,000 × 2,000 = 20 million input-token equivalents.
- Variable input: 10,000 × 800 = 8 million.
- Missed prefix input: 3,000 × 1,200 = 3.6 million.
- Cached prefix reads: 7,000 × 1,200 × 0.1 = 0.84 million equivalents.
- Prefix writes: 30 × 1,200 × 1.25 = 45,000 equivalents.
- Approximate total: 12.485 million instead of 20 million—a 37.6% reduction in input cost under these assumptions.
This is not a guaranteed saving. Short prompts, reordered tools, edited instructions and expired cache entries reduce reuse. Output, retrieval and external-tool costs remain outside the calculation.
Design the request for quality and economics
- Place stable material first. System instructions, style rules, tool schemas and durable quality examples belong in the reusable prefix.
- Place fresh data last. The user question, today’s prices, inventory and search results should not be buried in a supposedly stable block.
- Control versions. Small ordering changes can reduce reuse. Version the prefix instead of editing it informally.
- Separate tenants. Use keys and boundaries supported by the provider to prevent cross-customer accounting or data confusion.
- Create a bypass path. Sensitive, high-value or time-critical requests should bypass response caching even when a question looks familiar.
Connect savings to risk measurement
A smaller bill is not enough. The NIST AI RMF Measure playbook emphasizes purpose-specific metrics, post-deployment monitoring and acceptable error limits. The relevant economic metric is therefore cost per accepted outcome, not cost per API request.
Caching can complement AI model routing, but keep separate measures so savings can be attributed. Use a knowledge-freshness test to drive invalidation, pass changes through an AI release-risk gate, and record failures in the incident-learning log.
Design an experiment that exposes real savings
Randomly split eligible traffic between cached and control paths for long enough to cover peak and quiet days. Hold model, sampling settings and tools constant, then compare cost, latency and human acceptance. Do not compare a busy week with a quiet month; a changed request mix can manufacture apparent savings.
Maintain an invalidation log with the reason, timestamp and affected prefixes. Triggers include a changed returns policy, new price list, revised tool schema or an error found in a stable example. For application-level response caches, set expiry by domain sensitivity: a definition may remain valid far longer than a price or order status. Sample outputs after every update to confirm the retired version can no longer be served.
Rollback must be fast. If stale-answer complaints rise or tenant separation fails, the team should disable caching without disabling the assistant. That operational control is part of the ROI because it limits the loss when a cache design fails.
Dashboard and failure modes
Track cached tokens as a share of total input, input cost per accepted outcome, time to first token, stale-answer rejection rate, invalidation frequency, and sampled quality for cached versus uncached paths. The programme fails when hit rate rises but quality falls, when cache accounting or context crosses customer boundaries, or when teams avoid improving instructions because a change would reduce cache reuse.
Decision: choose one workflow with a long, repeated prefix and run a two-week controlled test. Keep caching only if accepted-outcome cost falls and latency improves without increasing staleness errors or data-boundary risk.
 Contact on WhatsApp